




In computing systems, copy-on-write is an optimization strategy that allows multiple callers to share the exact same data resource without duplicating it until someone attempts a modification [1]. Operating systems, programming language runtimes, and storage engines rely on this lazy allocation approach to avoid copying operations that waste memory and processor cycles. By keeping shared pages or blocks in a read-only state, the underlying manager postpones data duplication until a write request actually happens. This design keeps memory footprints lean during common tasks such as process creation and file snapshotting, though it introduces specific overheads when workloads begin modifying data heavily.
Core Mechanics of Copy-on-Write
The core logic of copy-on-write, also called implicit sharing or shadowing, rests on distinguishing between a shallow copy and a deep copy [1]. A shallow copy duplicates only a pointer and increments a counter. Making a deep copy is far slower, as the computer must duplicate every stored byte [3].
To preserve data integrity, the shared structure must enforce value semantics behind the scenes. Member functions like those in Qt inspect the reference count before modifying internal buffers. If the counter equals one, the caller already owns the sole reference and can apply edits in place without any copying overhead [3]. But if the reference count is greater than one, the runtime detaches the object by allocating a fresh data block, copying the current contents, and decrementing the original counter before writing [1].
This detachment mechanism guarantees that isolated components never observe unintended side effects from modifications made elsewhere in an application. Separate instances behave as independent values, yet they share storage until the precise moment their paths diverge. Because most data structures in everyday software are read far more often than they are rewritten, this deferred duplication saves large amounts of memory without compromising safety. Qt uses this principle across classes like QPixmap, QImage, and QPen to let developers pass graphics objects between functions without deep copy overhead. The programmer can treat separate instances as independent objects, while the underlying runtime quietly keeps memory consumption low until a drawing routine calls a modifying function like detach() [3].
Early Mainframe Origins in Paged Systems
Data sharing through paged memory tables took root during the mainframe era of the late 1960s. Early hardware like the IBM 360/67 supported paging and page faults. Storage keys caused imprecise exceptions. Because an imprecise exception prevented the operating system from resuming the program cleanly, designers could not use protection faults for page copying [2].
By roughly 1976, VM/370 R3 attempted an early form of copy-on-write by checking change bits in storage keys during context switches. Whenever a task modified a page, the supervisor marked that page as private and refreshed a copy from disk for other processes. This method was slow. It interacted poorly with the VM assist feature, and the 1971 S/370 Principles of Operation confirmed that hardware write faults were missing until ESA/390 added protection suppression in the mid-1990s for AIX/ESA [2].
The earliest widely used copy-on-write system was Tenex in 1972. It ran on a modified PDP-10. Tenex adapted the technique from BBN Lisp on the SDS 940 to save expensive core memory, later evolving into TOPS-20 on DEC 36-bit machines until DEC cancelled the product line in 1983. DEC added copy-on-write to VMS in 1979, while CMU built it into the Mach kernel in 1986, passing the code into 4.4BSD in 1994 to form the foundation of FreeBSD, NetBSD, and OpenBSD [2].
Virtual Memory and Page Faults
Operating system kernels cooperate with memory management units to orchestrate page sharing. When programs share address space, the kernel points virtual pages to identical memory frames and marks them read-only. As long as tasks only read data, memory bus requests proceed at full speed without kernel traps [1].
The moment a process executes a store command to a protected address, the memory management unit raises a page fault. It halts the instruction. The operating system intercepts this hardware interrupt, checks permissions, and recognizes that the page is marked for copy-on-write. If the frame has multiple references, the kernel allocates a clean frame from its free list, duplicates the four-kilobyte block, and updates the writing process’s page table entry with read-write permissions [1]. It decrements the reference count on the shared frame and resumes the faulted instruction, leaving the redirection hidden from user code.
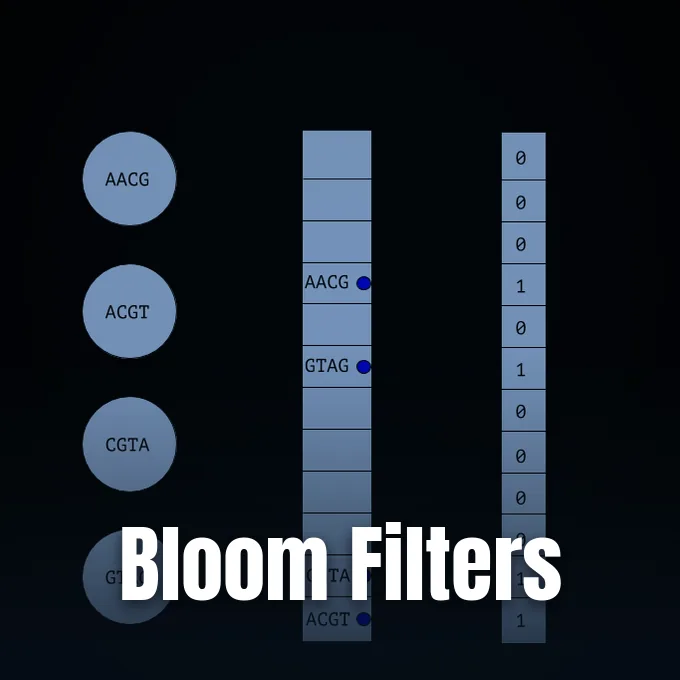
A related optimization applies this page fault routine to uninitialized memory allocations through a shared zero page. Instead of wiping separate memory blocks whenever software requests anonymous memory, the kernel points all newly allocated virtual pages to a single frame filled with zeros, marked as copy-on-write. RAM is never committed until the software actually writes bytes into an address, which allows sparse allocations and virtual address space overcommitment without consuming memory prematurely [1]. Linux also uses copy-on-write mechanics in its kernel same-page merging subsystem, scanning memory to merge identical anonymous pages. Systems programmers combine such memory virtualization features with compact indexing structures like Bloom filters to keep software memory footprints lean.
How Fork Uses Copy-on-Write
The best-known Unix role for copy-on-write arrives with the fork() system call. Classical Unix duplicated the entire parent address space for the child process. Because child processes usually invoke exec() right away to launch another binary, copying hundreds of megabytes was a huge waste of machine time [1].
Before copy-on-write arrived, developers introduced a temporary workaround. In 1979, 3.0BSD added vfork(), which lent the parent address space to the child until the child called exec() or exited. It avoided memory copying. But if the child modified stack variables before calling exec, it corrupted the parent’s state, creating tricky concurrency bugs that vanished once copy-on-write granted each process an independent memory view [2].
Even with copy-on-write in place, write-heavy workloads can encounter performance penalties after forking. Because the operating system resolves write faults one page at a time, thousands of writes force repeated kernel transitions that degrade system responsiveness. Researchers Ha and Kim (2022) studied this issue and designed an optimized scheme called CCoW, or coverage-based copy-on-write. CCoW measures spatial locality in address spaces to determine whether neighboring regions will soon experience writes. When high locality is detected, CCoW pre-copies multiple contiguous pages at once, cutting operating system intervention for write-intensive tasks and lifting overall application performance by up to 10% [7].
Software Runtimes and Object Types
Copy-on-write functions in application frameworks just as smoothly as it does inside operating system kernels. In Qt Core, classes such as QString, QVector, QByteArray, and QList use implicit sharing to handle resources without deep copies. Qt uses atomic compare-and-swap CPU instructions rather than mutexes to adjust reference counts safely across threads [3]. It avoids lock contention.
In PHP, variables rely on a container structure called a zval, which stores data types, values, and reference counts. The zval structure includes a refcount__gc counter and an is_ref__gc boolean flag. Passing an array with ten million elements into a function does not clone the elements; it merely increments the reference counter. Only when code modifies the array does PHP allocate a new zval, copy the elements, and reduce the original counter, while circular references are resolved by a built-in cycle collector using zval_gc_info and gc_root_buffer [4].
Rust provides a similar pattern through the Cow<'a, B> enum in its standard library, standing for clone-on-write. The enum holds either a borrowed reference or an owned value. Because Cow implements the Deref trait, programs can call read-only methods on borrowed data types like String, Vec, and PathBuf without allocating heap memory, invoking to_mut() to clone an owned copy only when modification is needed [5]. In contrast, the C++ language moved away from copy-on-write: while C++98 permitted copy-on-write implementations for std::string, the C++11 standard banned the practice because reference counting on multiple processor cores caused cache line bouncing and synchronization overhead [1].
Storage Layers in Copy-on-Write File Systems
Storage architectures adopt copy-on-write to escape the vulnerabilities of in-place block overwrites. In older file systems, editing a file meant modifying blocks where they lived. If power failed during an update, file tables suffered heavy corruption that required lengthy recovery tools like fsck to repair [1].
File systems like ZFS, Btrfs, APFS, ReFS, and Bcachefs write updates to unallocated blocks rather than overwriting live storage. They preserve existing data. When new blocks land on disk, the file system repoints parent metadata entries, allowing point-in-time snapshots to freeze root pointers with minimal storage overhead while untouched blocks stay shared between snapshots and active volumes. This out-of-place pattern also fits flash wear-leveling algorithms on solid-state drives [1].
Engineers often compare this block redirection to the sequential append design found in an LSM trees storage engine, where incoming writes are collected into memory buffers and flushed sequentially to disk. While both approaches prevent the corruption hazards of in-place overwrites, copy-on-write file systems maintain balanced tree structures that preserve random read performance in entire storage volumes. By writing new data to unallocated space before updating parent pointers, the file system ensures that an incomplete write never overwrites valid data. If a crash interrupts the process, the root pointer simply continues referencing the older, consistent tree state, providing instant recovery without lengthy log scans.
Container Layering with Storage Drivers
Container virtualization relies on copy-on-write storage drivers to run multiple lightweight environments from shared images. When an administrator starts many containers from one Docker image, duplicating filesystems would exhaust disk storage. Container engines stack read-only image layers underneath a thin writable layer, keeping container startup fast [1].
File-level copy-on-write is provided by union mounting systems such as OverlayFS, aufs, UnionFS, and GlusterFS [1]. When a container process reads a file, the union filesystem serves the data straight from the underlying read-only image layer. But when a process modifies that file, the storage driver copies the file up into the writable container layer before applying changes, an operation called copy-up [6]. If the container is later discarded, its writable layer vanishes while the shared base image stays untouched for other workloads [1].
Copying large files during runtime introduces noticeable input-output delays that can hinder container performance. Researchers Jiang, Liu, Shi, and Qiang (2020) analyzed this overhead in Docker storage drivers, observing that copying large files to the upper read-write layer created measurable runtime slowdowns. To eliminate this latency, they proposed DPSO, or Dynamic Prefetching Strategy Optimization. By analyzing container launch behaviors and predicting which files will undergo modifications, DPSO pre-copies target files into the writable layer at the start of container execution, achieving greater than 78% prefetch accuracy and effectively wiping out copy-up delays during application runs [6].
System Overhead from Recursive Updates
Despite its strengths in data protection, copy-on-write storage faces write amplification from recursive updates. In B-tree file systems like Btrfs, modifying a leaf block forces its parent node to update pointers. That parent update triggers its own copy-on-write, cascading pointer updates up the tree to the root [9].
Researchers Chen, Wang, Tan, and Xie (2014) evaluated these recursive updates in Btrfs, discovering that a single write can suffer up to 29.5 times write amplification and a 71% drop in throughput compared to update-in-place file systems. Under an email server workload, recursive updates produced 18.3 times write amplification and a 33% throughput reduction [9]. In their companion study, Chen and coauthors showed that write amplification varies between 1.1 and 4.2 times depending on file access distributions, file counts, and tree space utilization [10].
Storage researchers have devised smart caching and logging techniques to soften these write penalties. In virtualized cloud infrastructure, Fu and coauthors (2019) introduced COWCache to solve how copy-on-write virtual disks degrade flash cache endurance with unnecessary writes. By separating metadata management and decoupling amplified write requests, COWCache improves virtual machine input-output efficiency [8]. Similarly, for persistent memory file systems, Hwang and Won (2019) developed adaptive differential logging and zero-copy logging on NOVA and PMFS. Their hybrid technique applies logging when updates are smaller than half a block and copy-on-write for larger modifications, gaining roughly 150% throughput improvements over conventional copy-on-write [11].
- WEBSITE Wikipedia contributors. Copy-on-write. Wikipedia, The Free Encyclopedia. [Article Link]
- WEBSITE Levine, J. (2011). A history of copy-on-write memory management. Obvious Services. [Article Link]
- WEBSITE The Qt Company. (2019). Implicit Sharing. Qt Documentation. [Article Link]
- WEBSITE PHP Internals Book. Memory management: Reference-counting and copy-on-write. [Article Link]
- WEBSITE The Rust Project Developers. (2026). Enum Cow (clone-on-write smart pointer). The Rust Standard Library Documentation. [Article Link]
- ACADEMIC JOURNAL Jiang, Y., Liu, W., Shi, X., & Qiang, W. (2020). Optimizing the copy-on-write mechanism of docker by dynamic prefetching. Tsinghua Science & Technology, 26(3), 266-274. [Article Link]
- ACADEMIC JOURNAL Ha, M., & Kim, S. (2022). CCoW: Optimizing Copy-on-Write Considering the Spatial Locality in Workloads. Electronics, 11(3), 461. [Article Link]
- ACADEMIC JOURNAL Fu, J., Lu, Y., Shu, J., Liu, G., & Zhao, M. X. (2019). COWCache: effective flash caching for Copy-on-Write virtual disks. Cluster Computing, 23(2), 623-639. [Article Link]
- ACADEMIC JOURNAL Chen, J., Wang, J., Tan, Z., & Xie, C. M. (2014). Effects of Recursive Update in Copy-on-Write File Systems: A BTRFS Case Study. Canadian Journal of Electrical and Computer Engineering, 37(2), 113-122. [Article Link]
- ACADEMIC JOURNAL Chen, J., Wang, J., Tan, Z., & Xie, C. M. (2014). Recursive Updates in Copy-on-write File Systems – Modeling and Analysis. Journal of Computers, 9(10), 2342-2351. [Article Link]
- ACADEMIC JOURNAL Hwang, T., & Won, Y. (2019). Copy-on-Write with Adaptive Differential Logging for Persistent Memory. IEICE Transactions on Information and Systems, E102.D(12), 2451-2460. [Article Link]
Cover image: Qdrddr / Wikimedia Commons, CC BY-SA 4.0


